
When the WorldIs theTest Suite
Agentic Intelligence for the Physical World
The test suite does not ship with the code
Coding agents now write programs for robots, laboratories, and industrial controllers. Whether a program works can only be found out by running it on a robot, in a simulator, or through the policy it trains.
Writing programs is getting cheap. Trustworthy evidence about them is not.
Read the full abstract
Coding agents built to repair software now write, test, and repair programs for robots, laboratories, and industrial controllers. Unlike in software engineering, no test suite comes with the code. Whether a program works must be established by running it on a robot, in a physics simulator, or through the policies it helps to train, and such evidence is costly to obtain and can itself be wrong. As these agents take on more physical tasks, how their programs are judged matters as much as how they are written. This paper examines this emerging area, agentic intelligence for the physical world, by treating the world as the program's test suite.
We organize the discussion around three questions: how agents write programs for the physical world, how these programs are tested, and how agents learn from the results. We first trace how language models for robots and software engineering agents came together, ask which software testing practices carry over to physical tests, and describe each program by where it sits relative to the actuator and by what judges it. For writing, we cover programs that act as robot policies and programs that support policy learning by producing rewards, tasks, and training worlds. For testing, we examine what physical trials cost, what traces, learned judges, simulators, and formal checks can establish in their place, and what safety requires beyond task success. For learning, we discuss how tested programs are retained as experience, in skill libraries and in model weights. Finally, we turn to benchmarks and evaluation practice and outline open challenges. Writing programs is becoming cheap, while trustworthy evidence about what they do remains costly. Progress will therefore depend on a physical counterpart of continuous integration: verification cheap enough to run often, reliable enough to trust under search, and maintained alongside the experience it validates.
Where the loop breaks
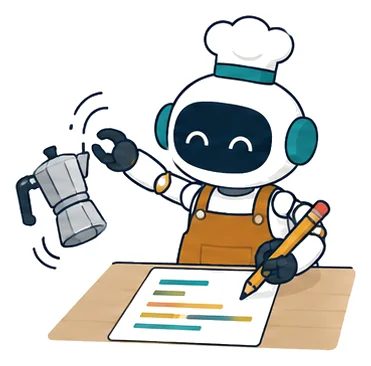
The agent's grasp aimed at the pot, not its handle. It rewrites the routine.
A program can only use the primitives it is given.
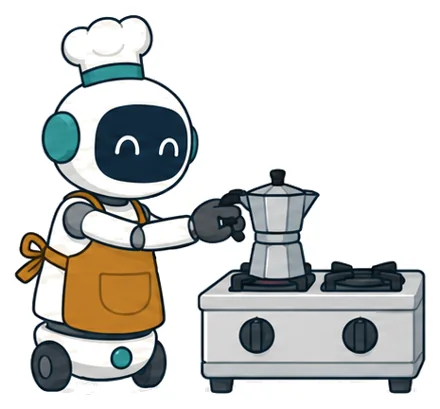
It runs the new program again from fifty starting states.
Every test costs an episode, a training run, or robot time.
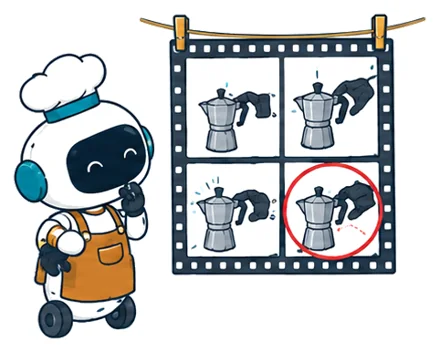
The pot is lifted. But is it on the burner, upright and stable?
Every kind of judge in use has documented failure modes.
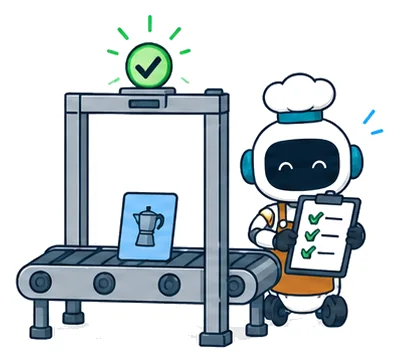
The fix goes into a skill library that other agents will read.
A library keeps whatever its acceptance test lets through.
Programs that act, and programs that teach
Some programs drive the robot or orchestrate learned skills. Others write the rewards, worlds and demonstrations a policy learns from.
Evidence is costly, and it can be wrong
What gets kept
Accepted programs become experience, in skill libraries and in model weights. A library keeps whatever its acceptance test lets through.
Where next
If the world is the test suite, its tests must be tested too.
Cost · Variance · Judge error · Judge visibility · Sim-to-real
What most reports leave out.
Cite
@article{li2026world,
  title   = {When the World Is the Test Suite: Agentic Intelligence for the Physical World},
  author  = {Li, Kaixin and Luo, Meng and Li, Yanlin and Tian, Yuchen and Liu, Xiang and Jian, Xiangru and Yang, Yan and Xi, Zhiheng and Zhang, Yang and Luo, Ziyang and Cheng, Mingfei and Lin, Hongzhan},
  journal = {arXiv preprint arXiv:2611.22291},
  year    = {2026},
  url     = {https://arxiv.org/abs/2611.22291}
}